What Is Crawl Budget?
Crawl budget is the attention and access that a search engine assigns to discovering and revisiting URLs on a website. The budget reflects how efficiently a site can be crawled and how valuable its pages appear to the search engine. It affects large or technically complex websites most directly.
Quick Facts About Crawl budget
Category
Technical SEO concept
Used for
Managing search-engine crawling
Common confusion
It does not guarantee indexing
Also called
Crawling budget
Often discussed with
Technical SEO, SEO Audits
Key Takeaways About Crawl budget
- Crawl budget concerns search-engine access, not ranking position.
- Clean site architecture helps crawlers reach important pages.
- Crawl budget is not the same as indexing or search visibility.
How Crawl budget Works
Crawl budget guides how a search engine allocates crawling activity across a website. Search-engine crawlers discover URLs through links, sitemaps and redirects, then decide which pages to request and revisit. A site with clear navigation and useful pages gives crawlers a more direct path.
Related glossary terms: Robots.txt, Noindex tag, Internal linking.
Technical conditions can consume crawling activity without helping users or search visibility. Duplicate URLs, long redirect chains, soft error pages and filter combinations may create unnecessary paths. Robots.txt can restrict selected areas, while a noindex tag controls whether a crawled page may enter the index. Crawl budget work therefore focuses on accessible, valuable URLs and removes avoidable crawling paths.
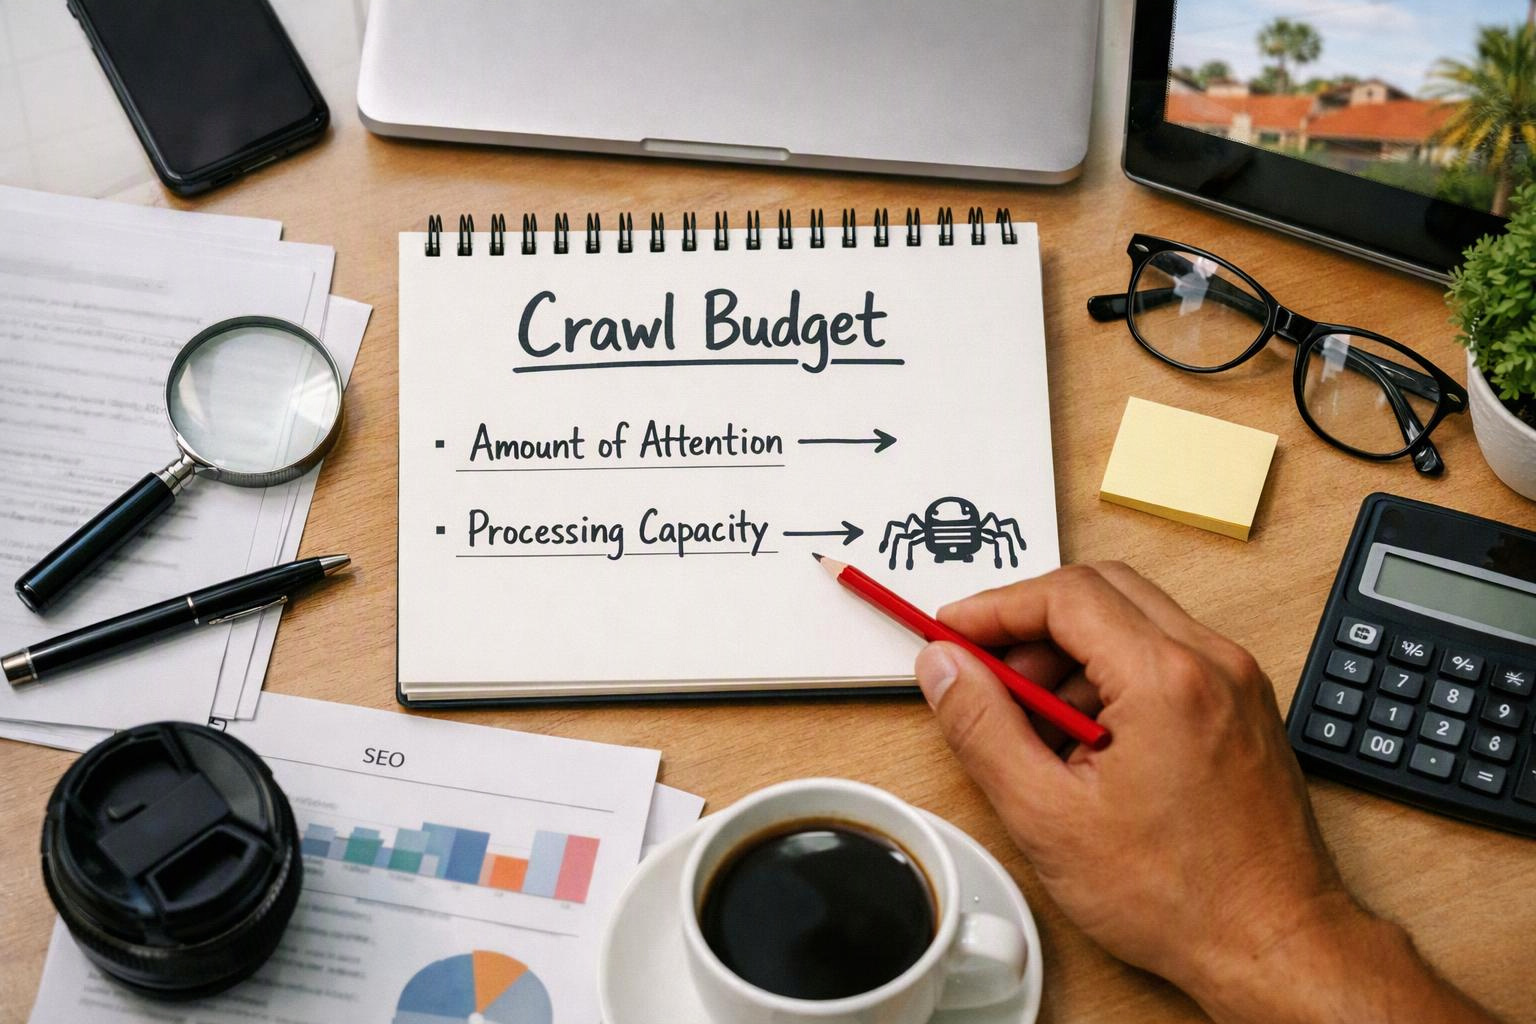
Expert Note
When we review crawl budget, we inspect crawl paths, indexable URLs, internal links, redirects and server responses. Our team then checks whether important legal service pages can be discovered without unnecessary duplicate or low-value URLs consuming crawler attention.
Crawl budget in Practice: A Real-World Example
A Sydney law firm may have separate URLs for practice areas, locations, tracking parameters and filtered blog views. Technical SEO work can consolidate duplicate paths and strengthen internal links so crawlers reach the firm’s key service pages more efficiently.
Related Services
Related Terms
Robots.txt
Robots.txt is a plain-text file that gives search engine crawlers instructions about which areas of a…
Noindex tag
A Noindex tag is an instruction that asks search engines not to include a webpage in…
Internal linking
Internal linking is the practice of connecting pages within the same website through clickable links. These…
Canonical tag
Canonical tag is an HTML link element that identifies the preferred version of a webpage when…
LawyerSeoMarketing.com.au
Have Questions About Crawl budget?
Contact LawyerSeoMarketing.com.au for practical guidance on Crawl budget and related lawyer seo marketing work in Sydney.